Status
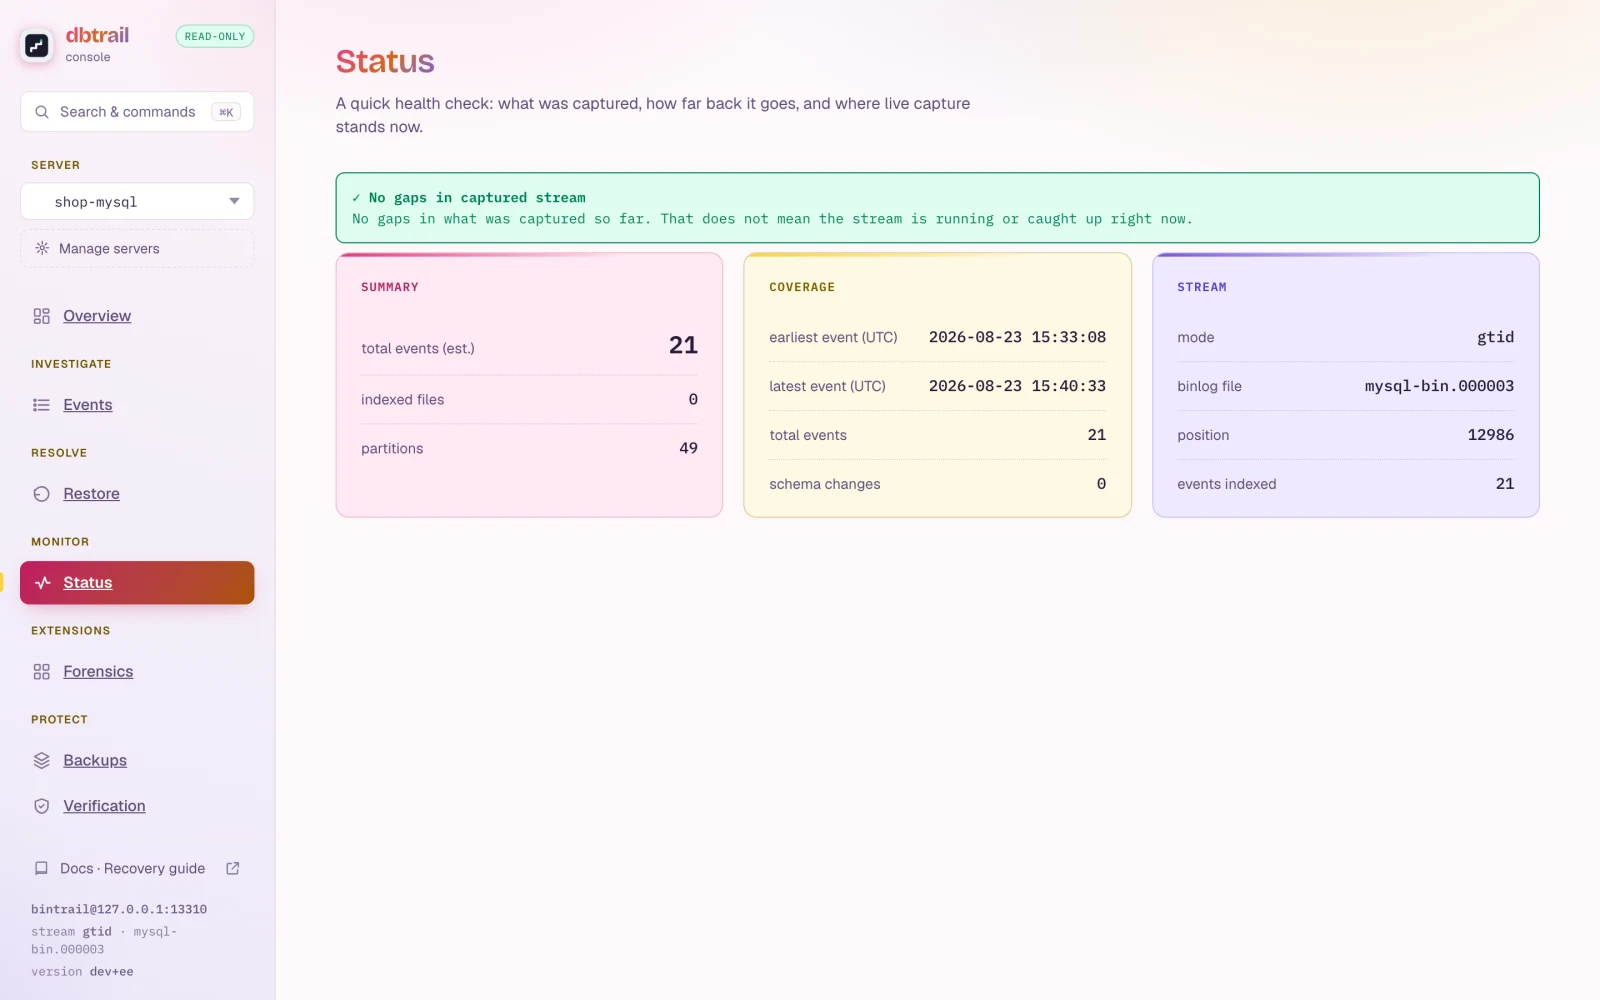
Where to look to know capture is running, nothing was lost, and the index disk will hold. Every stream state, what it means, what to do.
Web interface → Status, per server. Default address http://127.0.0.1:8090/.
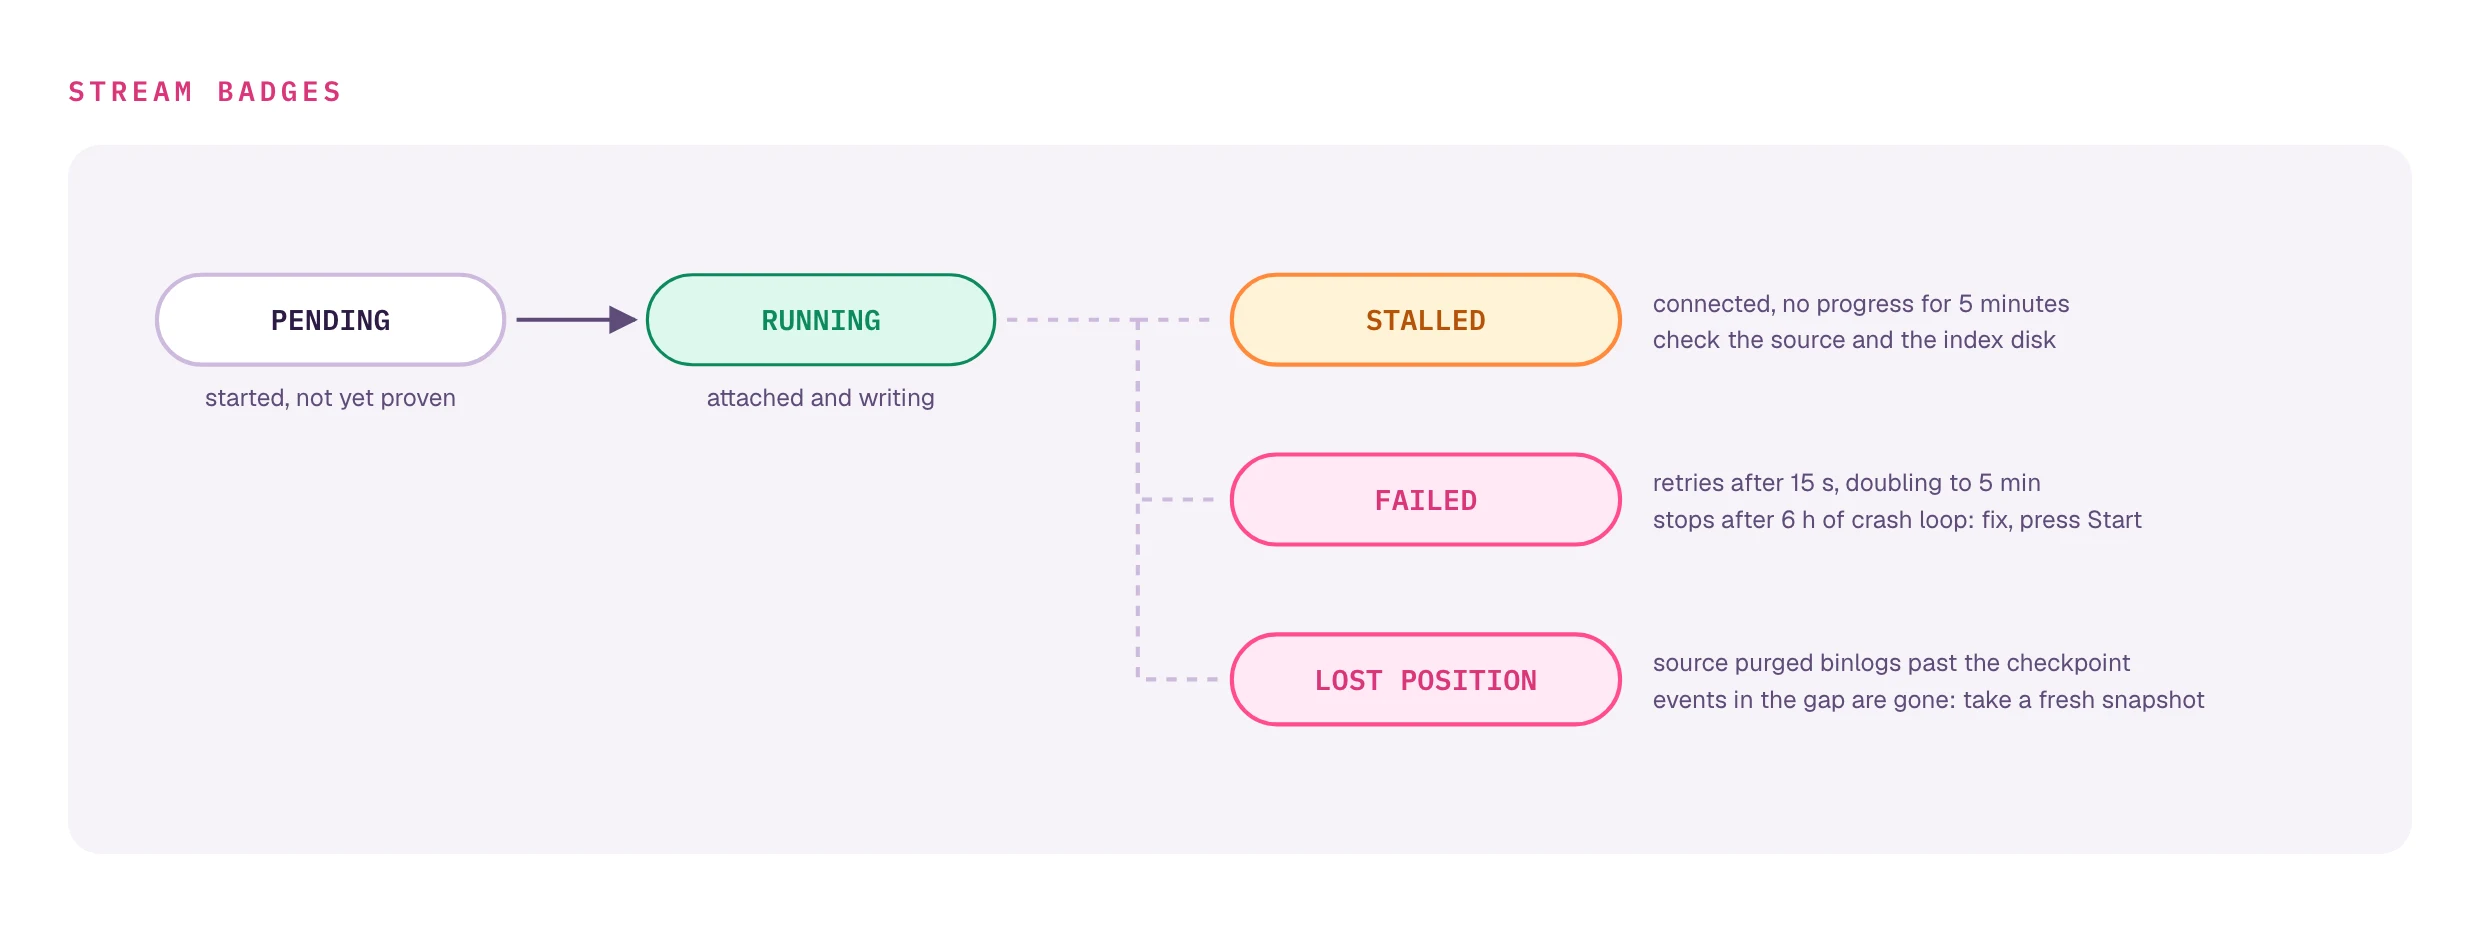
Stream states
- Restart: every stream resumes from its checkpoint. Nothing is lost while the source still has the binlogs.
- Crash: rows written after the last checkpoint (at most about 10 seconds)
are removed and read again, so nothing is stored twice. While that cleanup
runs the server's row reads CLEANING UP (since v0.83.0), the startup
checklist prints the step with rows removed and duration, and the stream
metrics already answer, with zeros, so alert on the age of
bintrail_stream_last_flush_timestamp_seconds, not onup. On a large index it takes minutes; before v0.83.0 it showed nothing at all. SIGTERMorSIGINT: streams stop, save a final checkpoint, exit.- Freshness: checkpoint every 10 seconds; a change is usually queryable within about 10 seconds of commit. What slows it: capacity planning.
- Falling behind: the Overview shows the copy's age as data as of HH:MM, counted from the newest change it holds, not from its last update. When the gap between the source and the index keeps widening for several minutes, the binlog arrow says falling behind and a card names the first things to check: the index MySQL's memory (Give the index MySQL memory) and the source's write rate.
Continuity
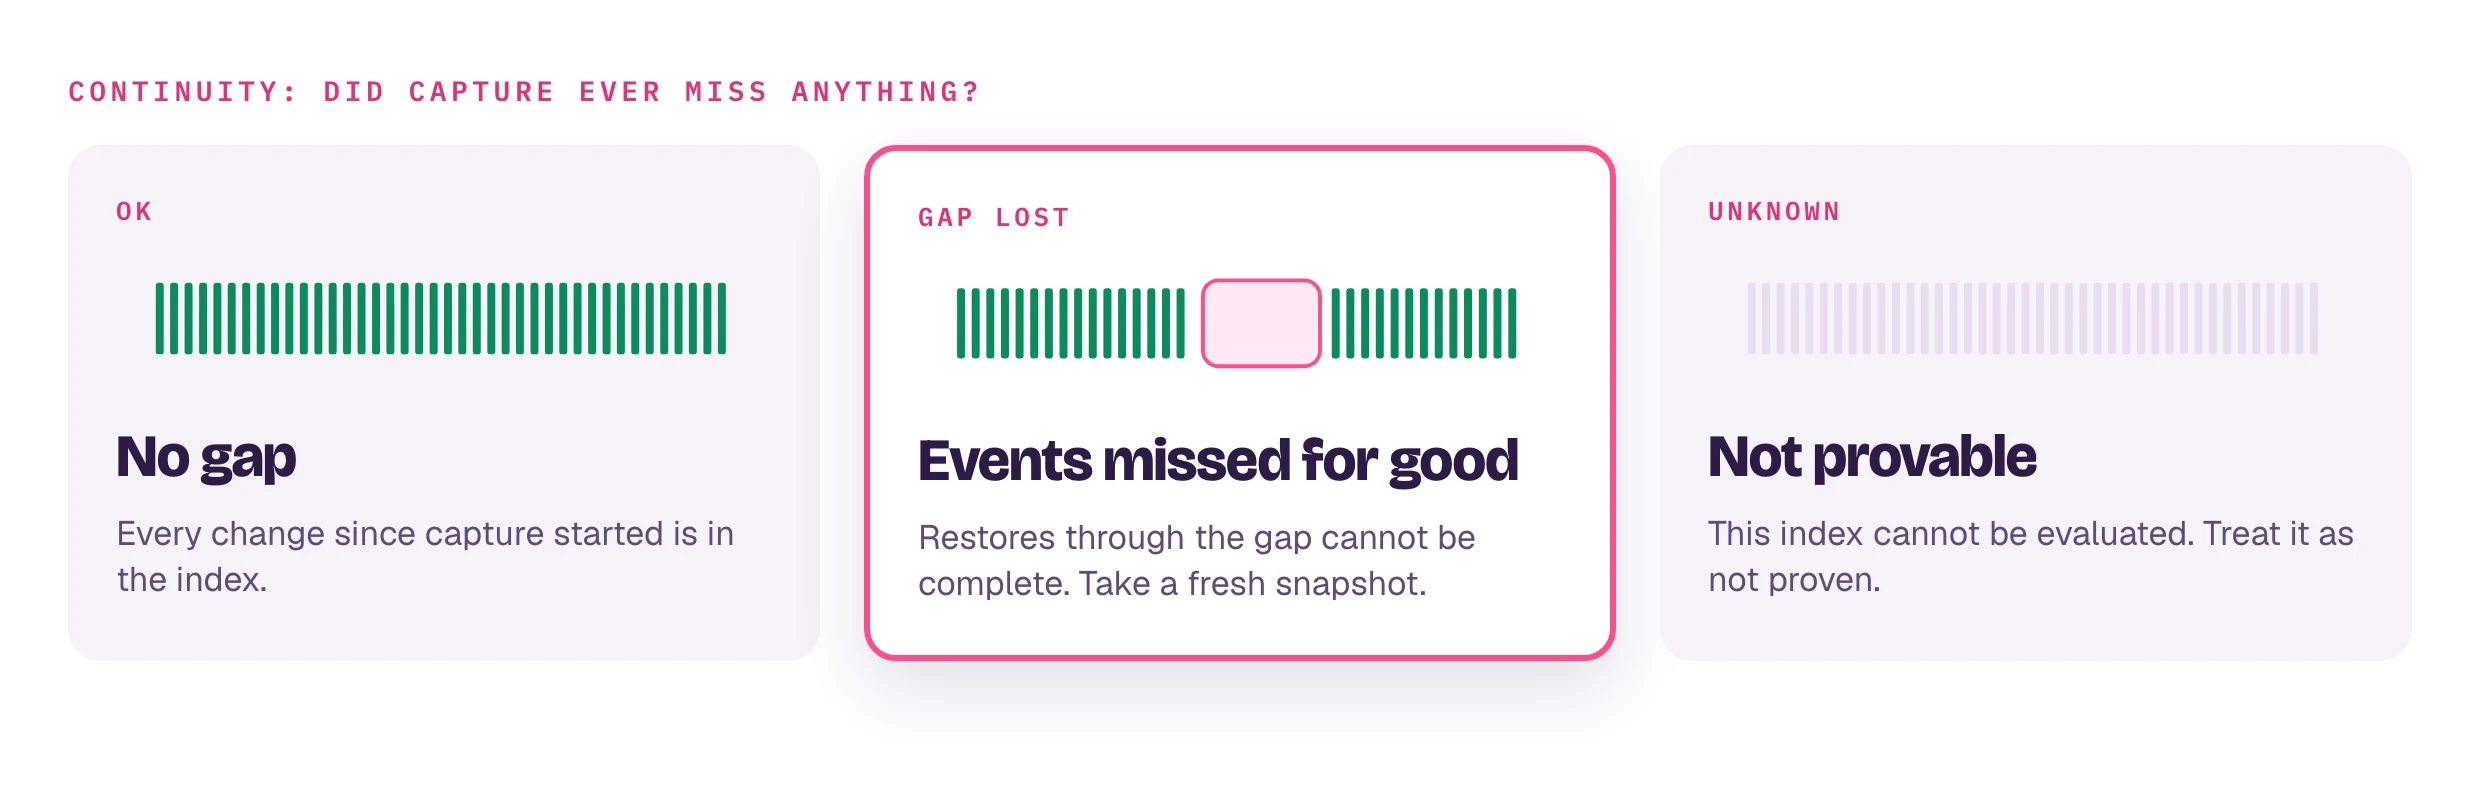
Same verdict in bintrail status --format json as continuity.status
(ok, gap_lost, unknown).
Index disk
The card shows size, write rate, settled size for your retention, free space and time until full. A warn or fail grade names the cause and the fix.
A full index disk loses data
A full volume stalls the stream. Once the source purges its binlogs, the gap is permanent. Alert first: Alerts.
Also showing health: Overview (restore coverage per table), Snapshots (newest snapshot, scheduled results), Snapshots → Checks (last runs).
Headless
bintrail status --index-dsn "$IDX" --format json    # last_event_time, last_checkpoint, continuity.status
bintrail status --index-dsn "$IDX" --fail-on-gap    # non-zero on a lost or unknown gap, for cron
bintrail doctor --source-dsn "$SRC" --index-dsn "$IDX"   # prerequisites, disk, days until full
GET /api/healthz: liveness, no auth. GET /api/status: the Status view as
JSON, access token required.
Rotation & status reference.